Case Study: Monte-Carlo Simulations
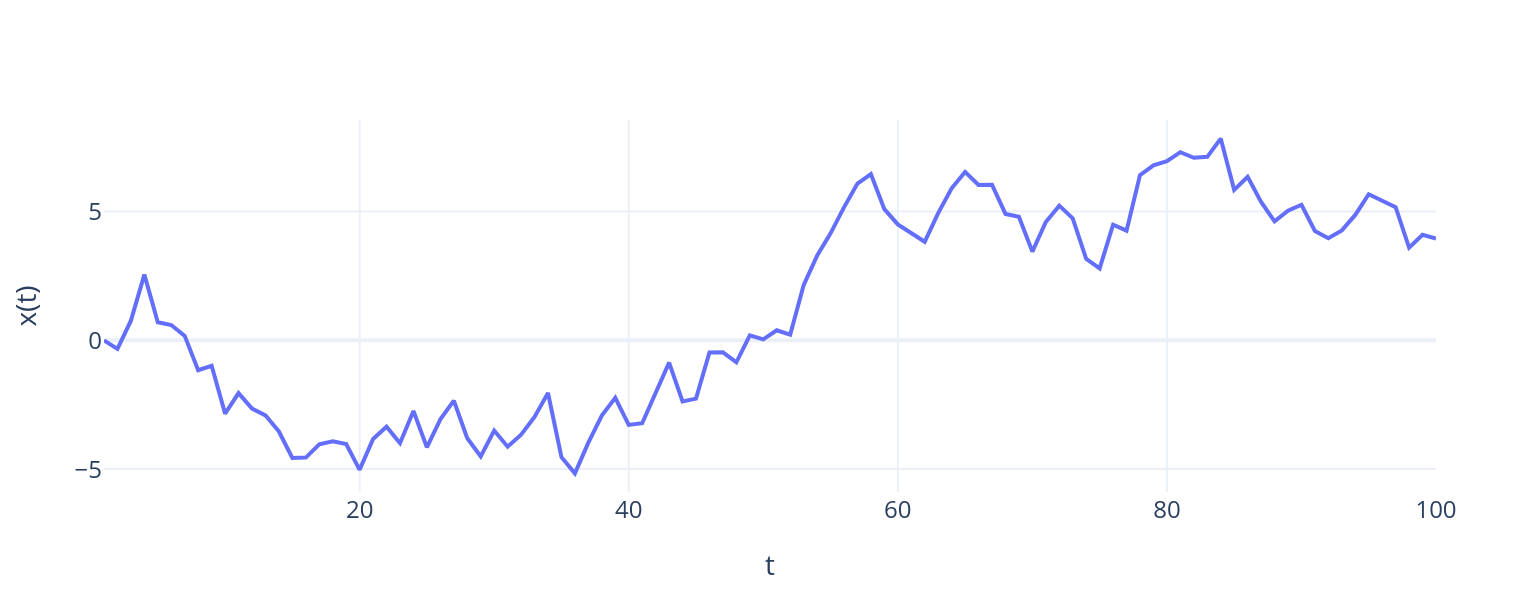
Here, we will provide an example of porting a Monte-Carlo random walk simulation to the GPU, such as the one shown in Figure 9.10.1. As with the earlier advice in this course, we will write a function that performs a single step in the random walk.
function mc_random_walk_step(x, sigma)
    return x + randn(typeof(x)) * sigma
end
Now imagine that we want to study some population level statistics, by running many of these walkers in parallel. Despite us choosing a very simple example, Monte-Carlo simulations are an extremely useful tool for computational science. Our aim for this exercise is to perform some number of steps of this Monte-Carlo update for many independent walkers and obtain an array with their final positions in.
We can implement a non-allocating array version of our desired algorithm:
function mc_random_walk!(y, x, sigma, steps)
    # Copy the initial values from x into y
    y .= x
    for t in 1:steps
        y .= mc_random_walk_step.(y, sigma)
    end
    return nothing
end
We can run our algorithm on the CPU easily:
n=2048; x = zeros(Float32, n); y = similar(x);
sigma = 1.0f0; steps=100;
mc_random_walk!(y, x, sigma, steps);
We can extend this to run on the GPU just by changing the types:
x_gpu = to_gpu(x); y_gpu = similar(x_gpu);
mc_random_walk!(y_gpu, x_gpu, sigma, steps);
Let’s benchmark the CPU version:
display(@benchmark mc_random_walk!($y, $x, $sigma, $steps))BenchmarkTools.Trial: 10000 samples with 1 evaluation per sample.
Range (min … max): 444.979 μs … 536.378 μs ┊ GC (min … max): 0.00% … 0.00%
Time (median): 493.264 μs ┊ GC (median): 0.00%
Time (mean ± σ): 493.789 μs ± 7.684 μs ┊ GC (mean ± σ): 0.00% ± 0.00%
▁▄▆▇███▇▅▅▄▄▂▁
▂▂▁▁▁▁▂▁▁▂▁▁▂▂▁▂▁▂▁▁▁▁▂▁▁▁▂▃▃▅▅▅▅▅▆▆███████████████▇▆▅▅▄▄▃▃▃▃ ▄
445 μs Histogram: frequency by time 514 μs <
Memory estimate: 0 bytes, allocs estimate: 0.And the GPU version:
display(@benchmark begin
    mc_random_walk!($y_gpu, $x_gpu, $sigma, $steps)
    gpu_synchronize($y_gpu)
end)BenchmarkTools.Trial: 10000 samples with 1 evaluation per sample.
Range (min … max): 235.874 μs … 2.266 ms ┊ GC (min … max): 0.00% … 87.98%
Time (median): 241.348 μs ┊ GC (median): 0.00%
Time (mean ± σ): 260.964 μs ± 162.860 μs ┊ GC (mean ± σ): 5.60% ± 7.84%
▃▇██▇▆▅▅▃▂▂▂▁ ▁ ▁▃▃▄▄▃▂▂▁▁ ▂
▃▇████████████████▇██▇▇▆▇▇▆▅▆▆████████████▇▇▇▇▇▇▆▅▅▅▅▅▅▂▂▂▂▅▄ █
236 μs Histogram: log(frequency) by time 290 μs <
Memory estimate: 189.41 KiB, allocs estimate: 3738.We see that our GPU version is actually faster (for this number of walkers), however, there is actually a bit of a performance bug under hood that should be addressed. Upon each of our for loops, we are calling a new kernel. Instead, we should try to fuse these kernels together:
function mc_random_walk(x, sigma, steps)
    for t in 1:steps
        x = mc_random_walk_step(x, sigma)
    end
    return x
end

function mc_random_walk_fused!(y, x, sigma, steps)
    y .= mc_random_walk.(x, sigma, steps)
    return nothing
end
Now we can try and benchmark this again:
display(@benchmark begin
    mc_random_walk_fused!($y_gpu, $x_gpu, $sigma, $steps)
    gpu_synchronize($y_gpu)
end)BenchmarkTools.Trial: 10000 samples with 1 evaluation per sample.
Range (min … max): 46.890 μs … 4.054 ms ┊ GC (min … max): 0.00% … 97.91%
Time (median): 47.464 μs ┊ GC (median): 0.00%
Time (mean ± σ): 47.897 μs ± 40.071 μs ┊ GC (mean ± σ): 0.83% ± 0.98%
▁▃▄▄▆▇█▇█▆█▅▆▄▂▁▁
▂▂▂▂▂▂▂▂▂▂▂▃▃▄▅▆██████████████████▇▆▅▅▄▄▃▃▃▃▂▂▂▂▂▂▂▂▂▂▂▂▂▁▂ ▄
46.9 μs Histogram: frequency by time 48.2 μs <
Memory estimate: 2.03 KiB, allocs estimate: 38.We have fused all the kernel calls together. This minimises the amount of overhead for scheduling, and allows the GPU cores to stay busy for the duration of the computation. This small change allowed us to dramatically improve the performance of our GPU code.
If the kernel calls are very large (e.g. a large matrix multiply), the overhead in calling multiple kernels is only a very small portion of the total time.
Custom Kernel
It is a good exercise to write a custom kernel and compare the execution to the broadcasted notation. Our kernel will be straightforward:
@kernel function mc_random_walk_kernel!(y, x, increments, sigma, steps)
    i = @index(Global, Linear)
    if i <= length(y)
        @inbounds pos = x[i]
        for t in 1:steps
            @inbounds pos += increments[i, t] * sigma
        end
        @inbounds y[i] = pos
    end
end

function mc_random_walk_gpu!(y, x, sigma, steps)
    @assert length(y) == length(x)
    increments = to_gpu(randn(eltype(x), length(x), steps))
    backend = get_backend(y)
    mc_random_walk_kernel!(backend, 256)(y, x, increments, sigma, steps; ndrange=length(y))
    return nothing
end
We can now benchmark on the same data:
display(@benchmark begin
    mc_random_walk_gpu!($y_gpu, $x_gpu, $sigma, $steps)
    gpu_synchronize($y_gpu)
end)BenchmarkTools.Trial: 7377 samples with 1 evaluation per sample.
Range (min … max): 630.188 μs … 1.695 ms ┊ GC (min … max): 0.00% … 0.00%
Time (median): 645.716 μs ┊ GC (median): 0.00%
Time (mean ± σ): 677.512 μs ± 113.067 μs ┊ GC (mean ± σ): 3.77% ± 9.15%
██▇▆▅▄▂▁ ▂
█████████▇▆▆▆▆▇▇▅▆▅▅▅▅▁▃▃▁▃▁▁▁▁▁▁▁▁▁▁▅▆▆▇▇▇▇▆▆▆▇▇▇▆▇▇█▇███▇█▇ █
630 μs Histogram: log(frequency) by time 1.18 ms <
Memory estimate: 801.77 KiB, allocs estimate: 33.We can see that our custom kernel did not perform as well as our simpler approach. It is clear that writing a custom kernel is not necessary to achieve performance gains, as we can rely on the compiler to generate fast code for the GPU, using the array notation. It is entirely possible to rewrite our kernel to be of a similar performance to our previous implementation, but this would require more effort on our part.